Stealth Models · Independent AI benchmarks

StealthMark 1.8.8

Original tests no model could study for.

Physical and spatial reasoning, planning across many steps, and turning ideas into precise visuals. Every score on this page comes with the result behind it.

Results as of 28 October 2026

See the scoresSee the evidence

Loading map

Compare any two models

Every benchmark side by side, with the results behind each score.

First model

First model
Second model
74.7
Benchmark score
59.2
73.4
General Intelligence
56.8
77.0
Visual Intelligence
63.5

Compare on stealthmodels.com

Scores

What the scores mean
Benchmark score
How well a model's abilities carry over to original, demanding tasks in reasoning, planning and visual work, as one score from 0 to 100. A high score means its skills hold up beyond familiar benchmark questions.
General Intelligence
The ability to reason, plan, solve problems and understand how things relate and behave. A high score means it thinks hard problems through, from careful analysis to plans that span many steps.
Visual Intelligence
The ability to understand visual intent and turn ideas, descriptions and plans into coherent, effective visuals. A high score means design ideas come out the way you meant them.
Model
74.773.477.0
72.671.375.0
70.267.076.1
67.864.474.1
67.463.674.4
63.362.764.5
63.060.667.1
62.658.769.6
60.458.064.9
59.256.863.5
57.053.164.0
56.753.962.0
54.151.958.2
51.746.161.6
51.746.261.4
50.644.461.4
50.048.553.0
49.547.652.8
48.542.359.4
47.943.955.2
47.944.354.3
47.248.444.8
46.638.560.3
45.935.862.6
45.841.952.7
45.535.764.4
45.137.657.2
44.641.049.8
44.142.646.6
43.941.348.6
43.334.458.0
42.235.551.2
41.841.642.3
41.334.353.1
39.838.342.3
39.131.352.0
39.037.141.9
37.830.450.2
36.536.636.3
34.628.045.3
32.425.643.9
31.930.933.8
27.625.531.1
25.819.136.7
20.812.734.0
19.211.731.0
18.912.029.8
16.712.226.5
16.59.428.9
14.17.424.6
10.97.915.6
Partial results
Callstack ApexPartial coverage
Partial coverage

Not scored in Foresight

49.540.459.6
Fledge AlphaSuspected routerPartial coverage
Partial coverage

Not scored in Foresight, Latch

35.827.145.2
LongCat-2.0Partial coverage
Partial coverage

Not scored in Foresight, Latch

25.517.234.4
Kolibri-1Partial coverage
Partial coverage

Not scored in Foresight, Latch

13.612.315.0

View the full results

See the evidence

Each benchmark below shows its highest and lowest scoring result, so you can judge the gap yourself.

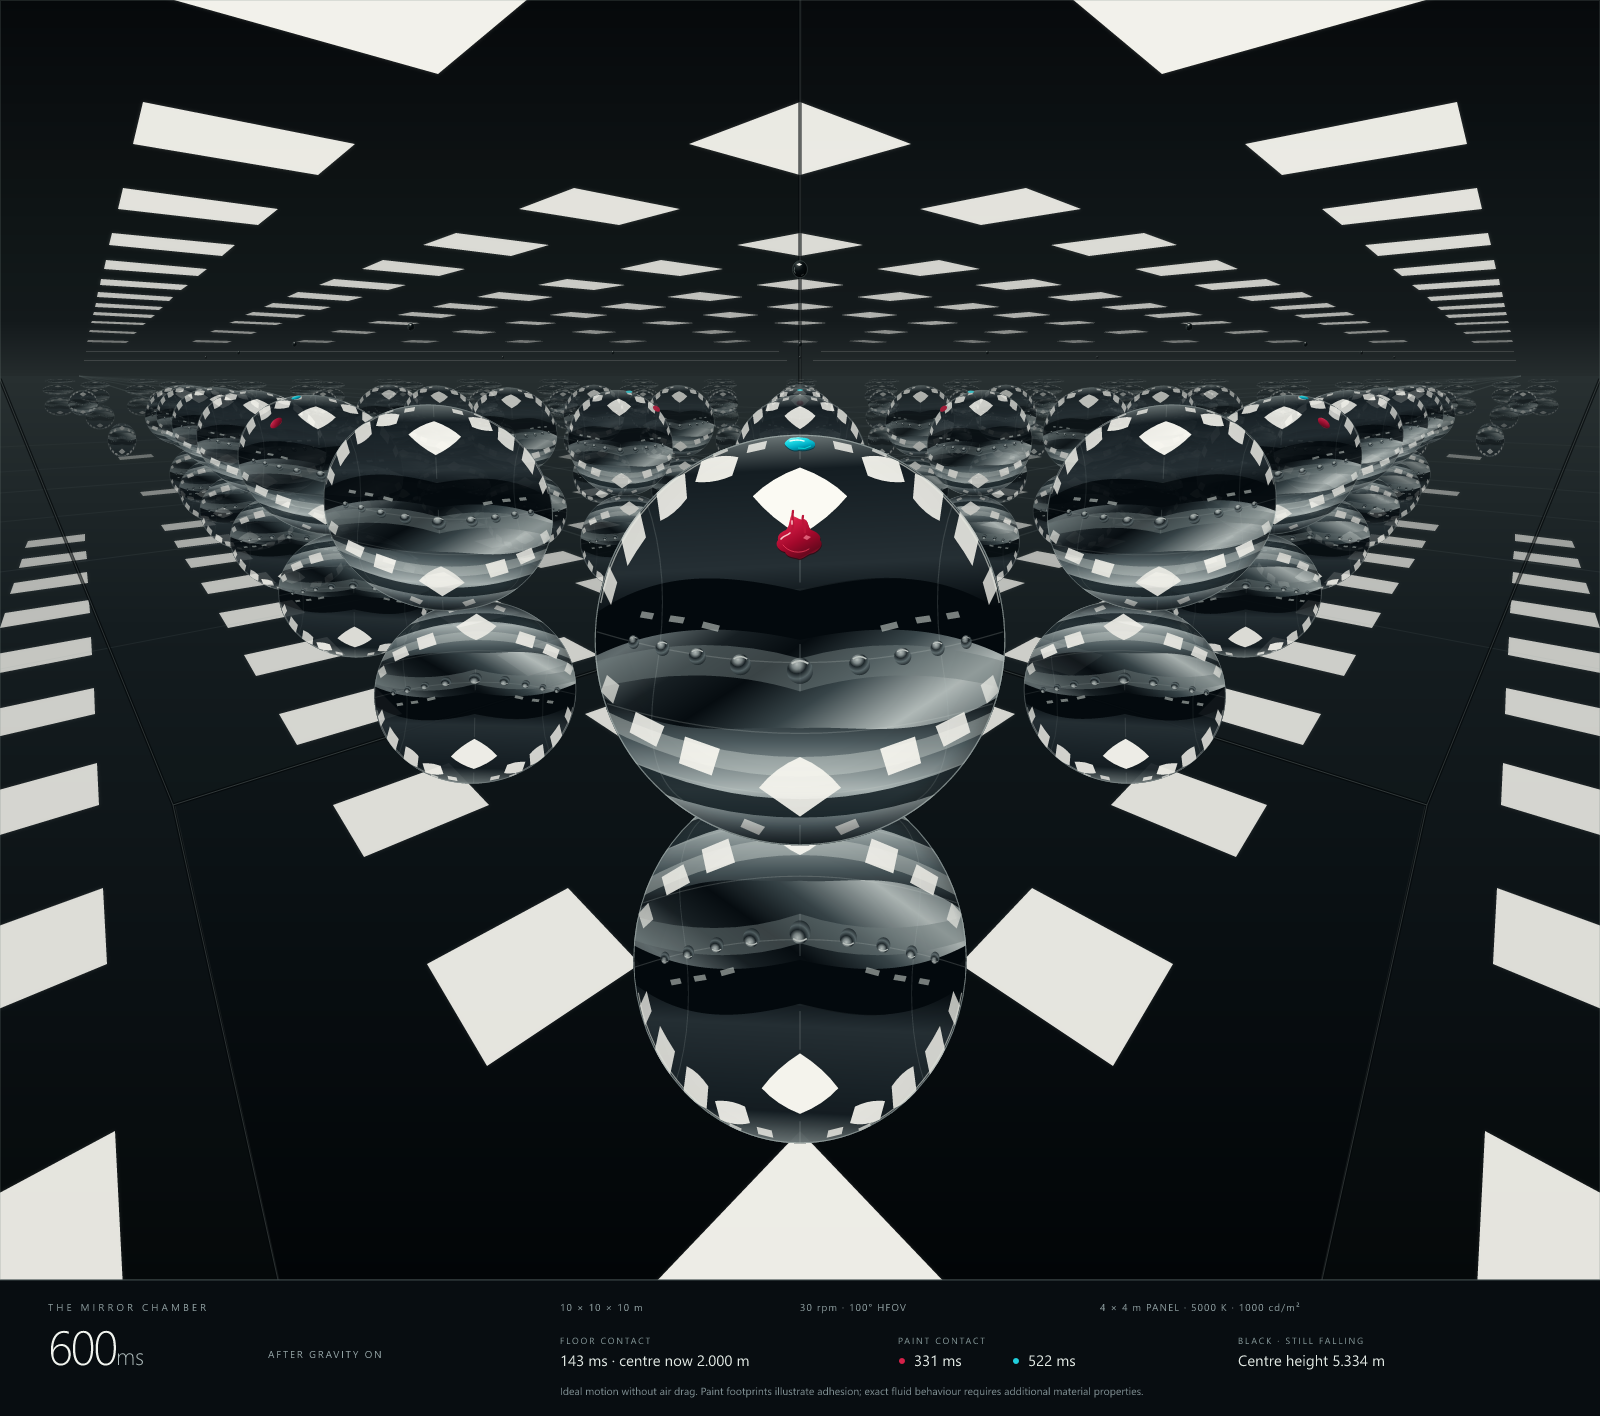
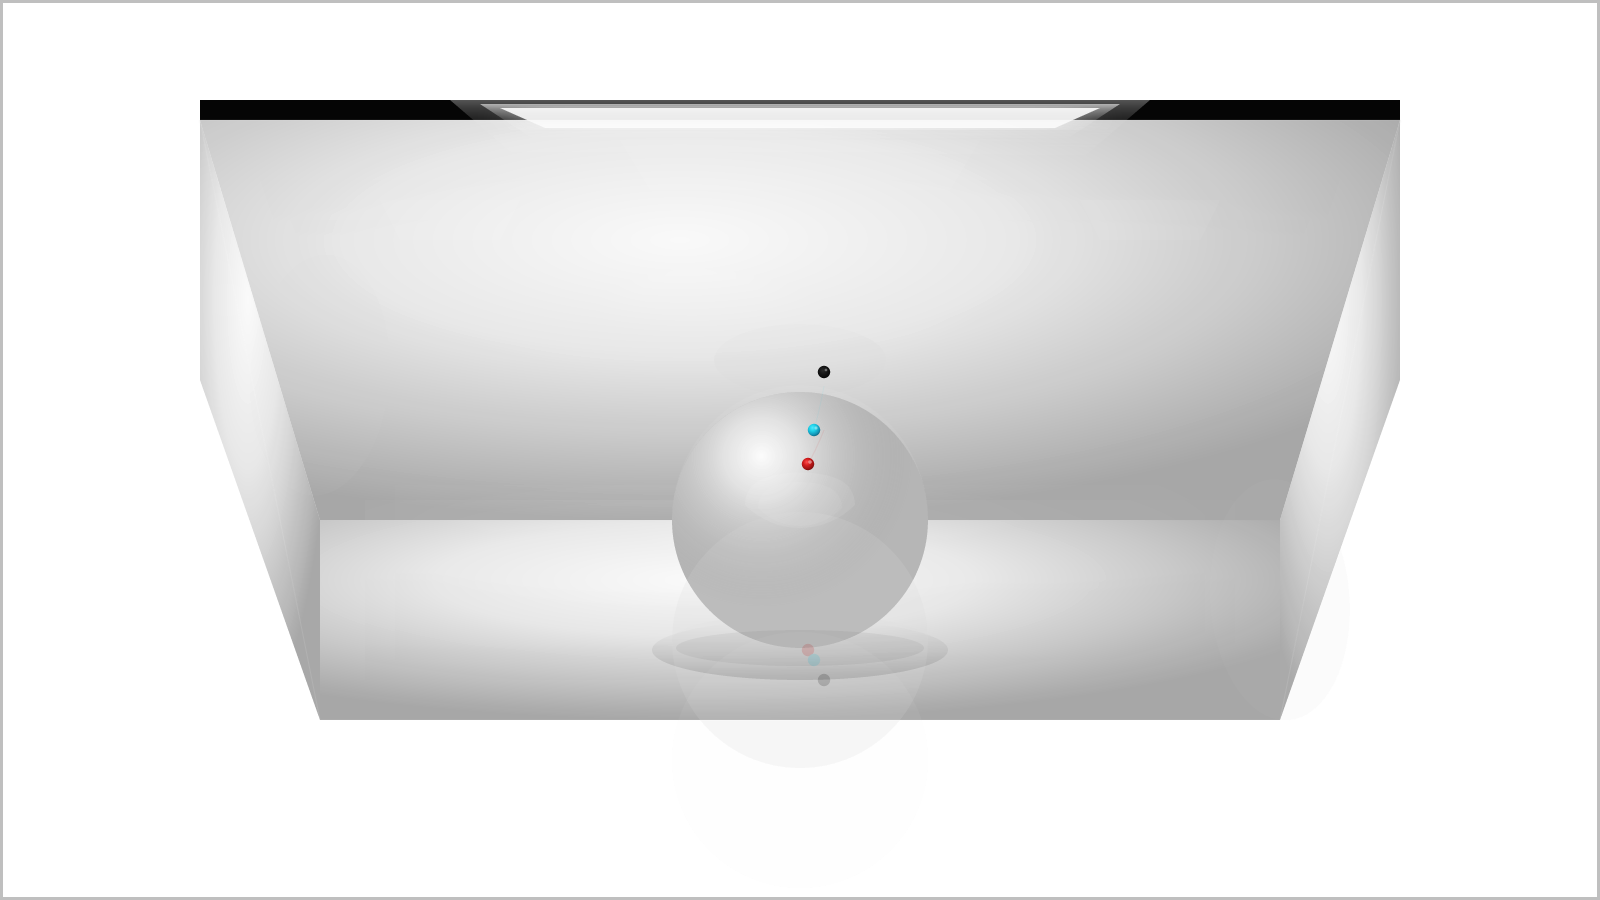
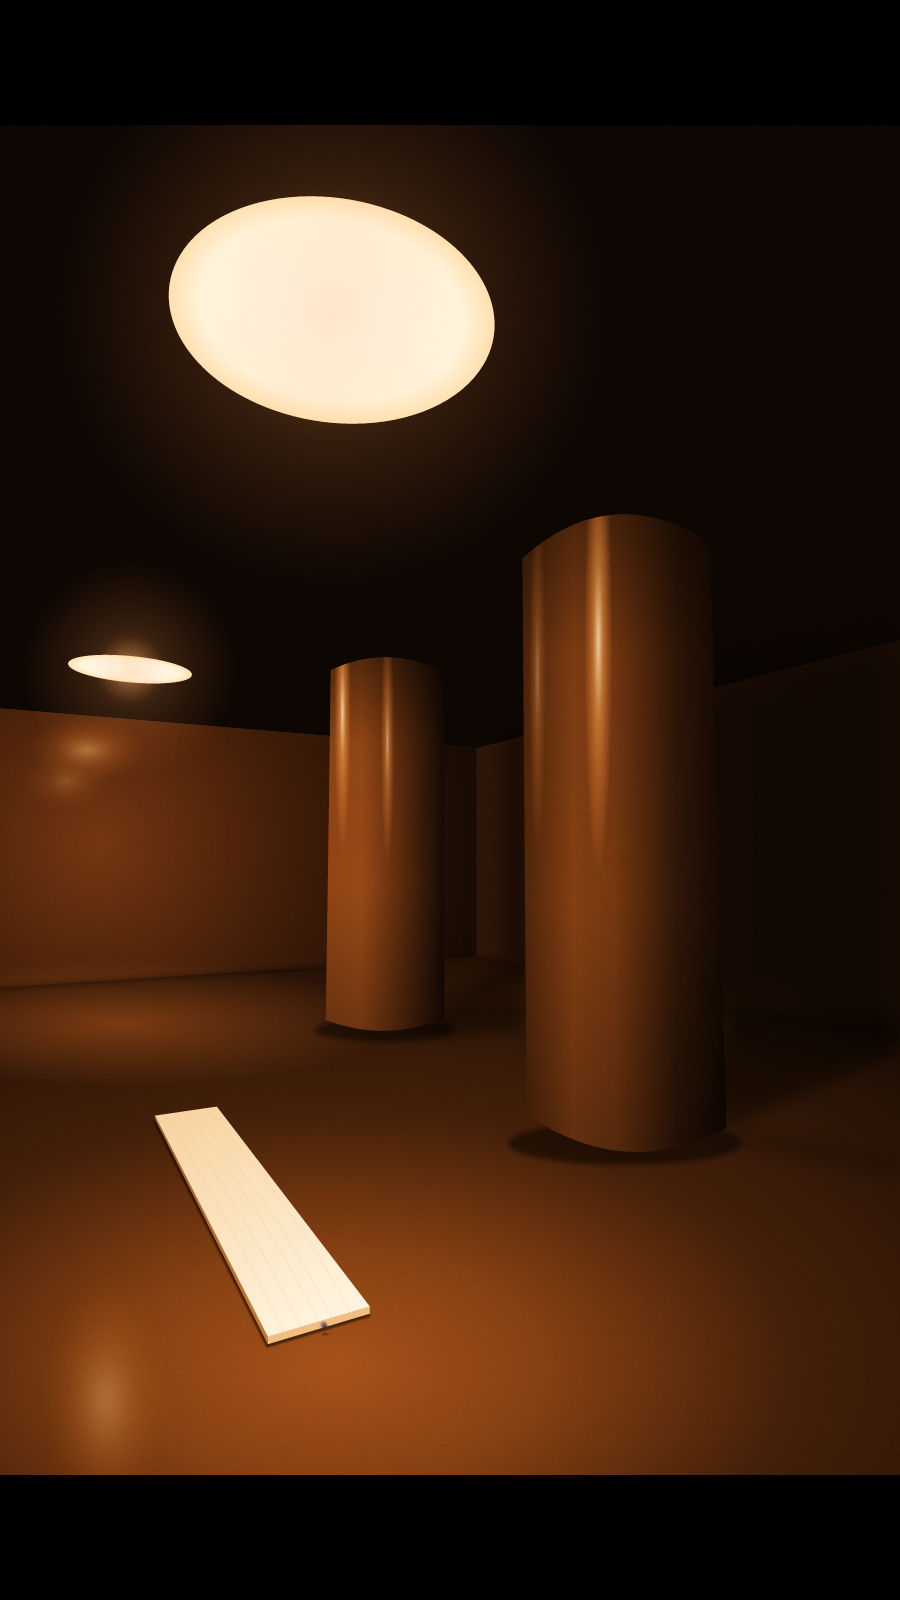
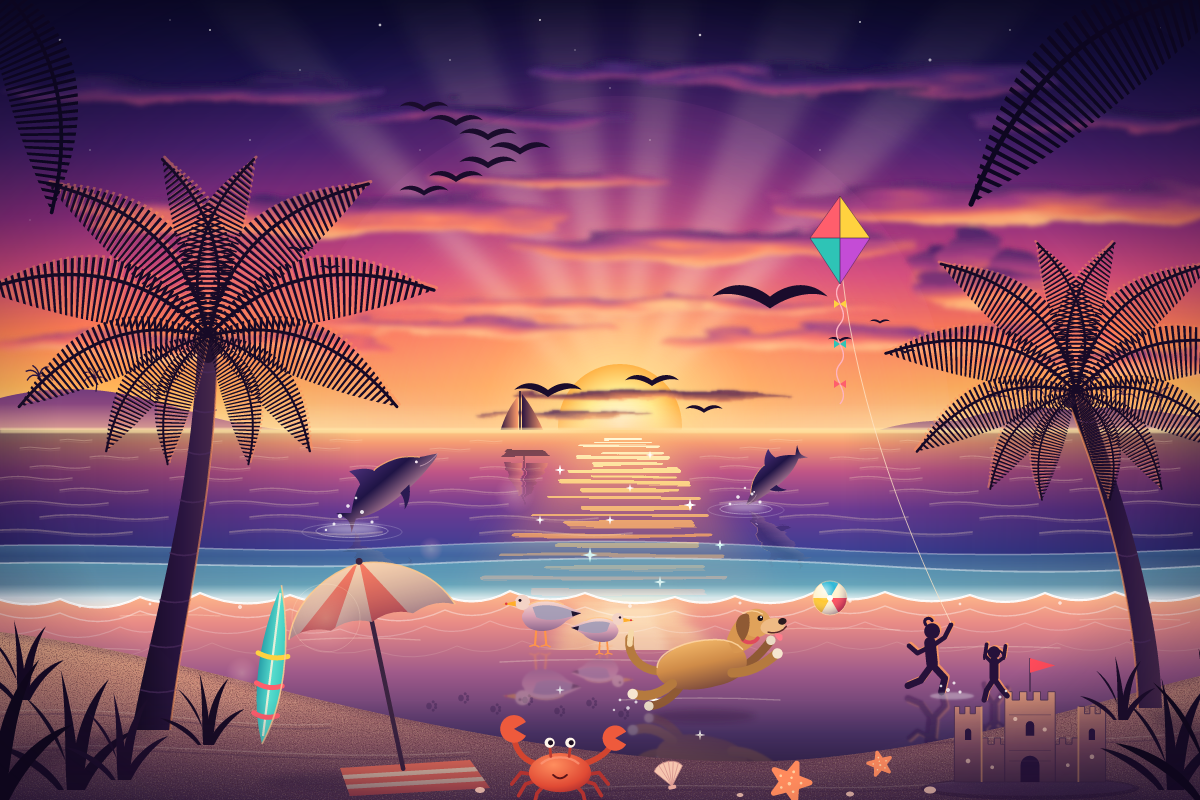
Newton's Mirror: Can a model trace light through a hall of mirrors in its head, with no code to do the maths?

A high score means the physical state, geometry and repeated reflections remain consistent.

Reference
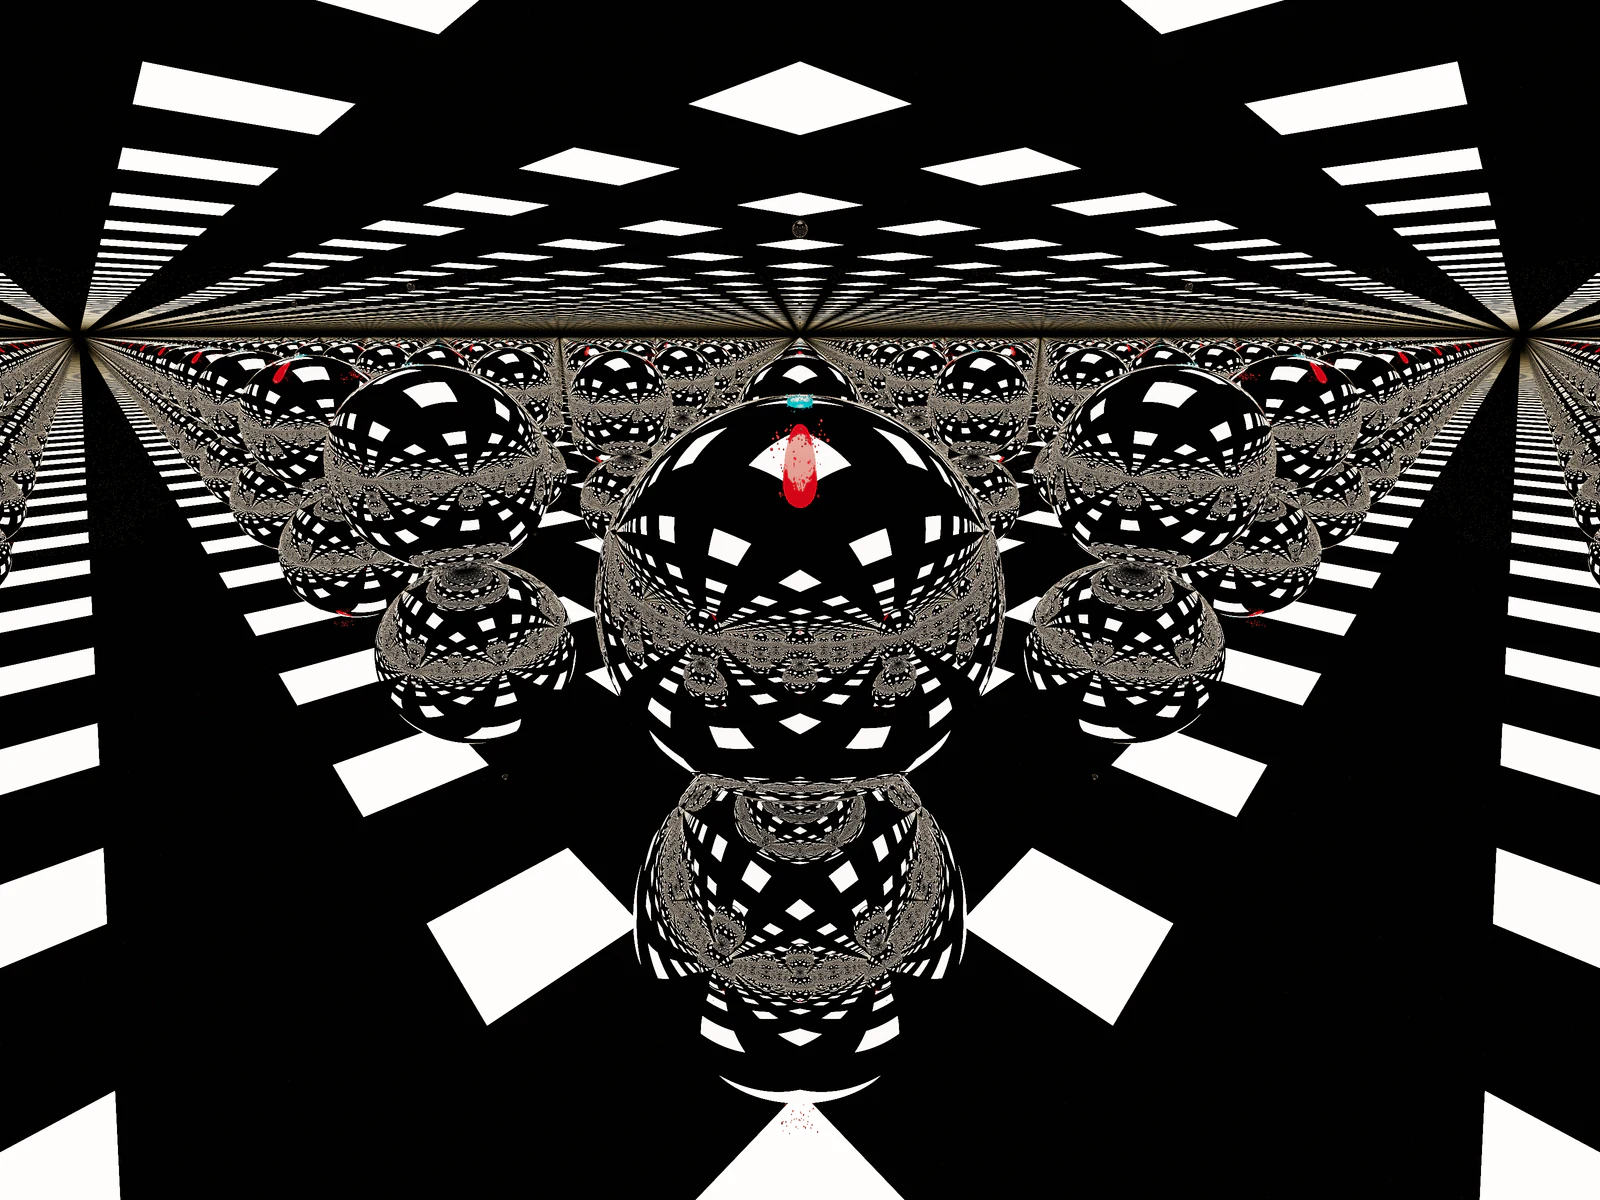
Reference for Newton's Mirror

Highest score

GPT-6 Astra: Newton's Mirror benchmark result

Benchmark score: 70.6 out of 100

Recorded 30 September 2026View result · GPT-6 Astra, Newton's Mirror

Lowest score

MAI-Thinking-1: Newton's Mirror benchmark result

Benchmark score: 8.0 out of 100

Recorded 9 October 2026View result · MAI-Thinking-1, Newton's Mirror

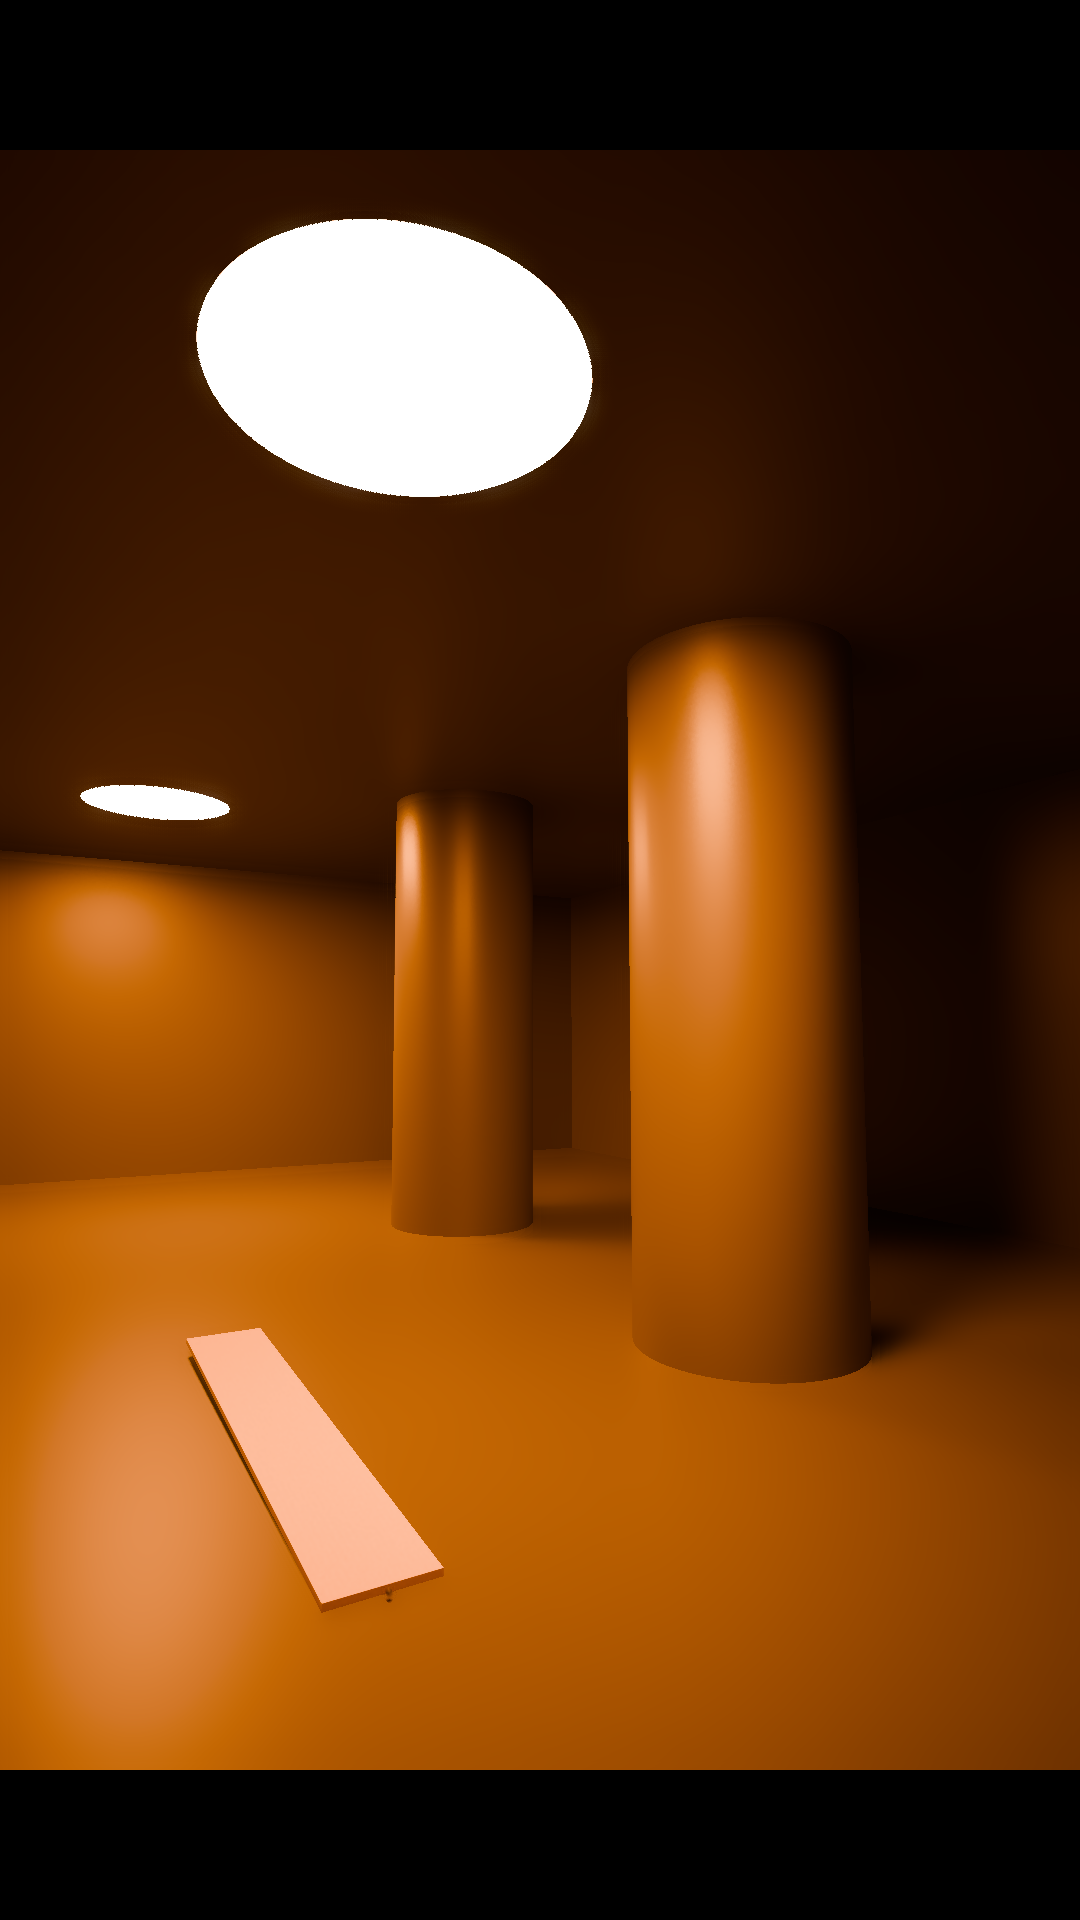
Ground Truth: Can a model reason through a scene where every detail depends on another?

A high score means the model follows how placement, materials and light affect one another.

Reference
Reference for Ground Truth

Highest score

Claude Opus 5.5: Ground Truth benchmark result

Benchmark score: 80.6 out of 100

Recorded 6 October 2026View result · Claude Opus 5.5, Ground Truth

Lowest score

MAI-Thinking-1: Ground Truth benchmark result

Benchmark score: 1.9 out of 100

Recorded 9 October 2026View result · MAI-Thinking-1, Ground Truth

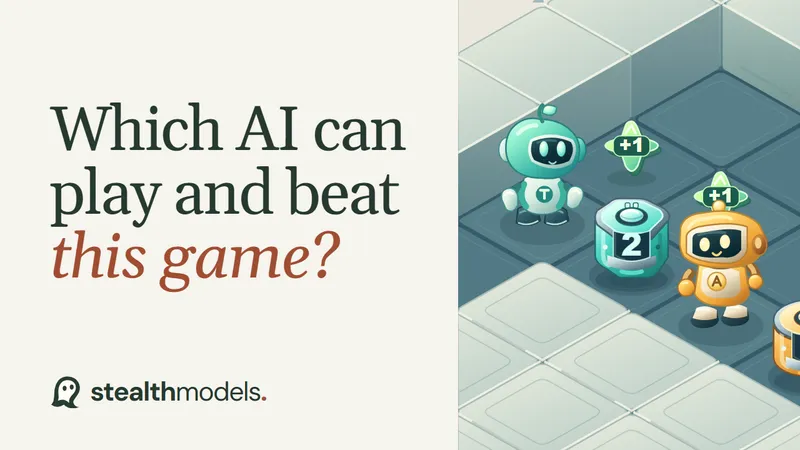
Latch: Can a model find the best plan, not just a plan, and get better at it level by level?

A high score means the robots coordinate efficiently, avoid irreversible mistakes and improve across levels.

Highest score on the full chain

Claude Opus 5.5: Latch, level 5

Benchmark score: 87.6 out of 100

5 of 5 levels completed

  • Level 1 · Cleared · 5.2 points
  • Level 2 · Cleared · 10.2 points
  • Level 3 · Cleared · 19.2 points
  • Level 4 · Cleared · 18.2 points
  • Level 5 · Cleared · 20.6 points

Watch the replay · Claude Opus 5.5, Latch

Lowest score on the full chain

Glyph Cluster: Latch, level 5

Benchmark score: 3.6 out of 100

5 of 5 levels completed

  • Level 1 · Cleared · 5.2 points
  • Level 2 · Out of turns · 2 points
  • Level 3 · Finished early · 4.2 points
  • Level 4 · Out of turns · 1 points
  • Level 5 · Finished early · 9 points

Watch the replay · Glyph Cluster, Latch

Foresight: Can a model stay one step ahead of the ghosts?

A high score means the model collects points while anticipating where the ghosts will move.

Highest score on the full chain

GPT-6 Astra: Foresight, level 3

Benchmark score: 76.1 out of 100

3 of 3 levels completed

  • Level 1 · Survived · 27 points
  • Level 2 · Survived · 11 points
  • Level 3 · Survived · 18 points

Watch the replay · GPT-6 Astra, Foresight

Lowest score on the full chain

Iceman Contributor: Foresight, level 3

Benchmark score: 3.2 out of 100

3 of 3 levels completed

  • Level 1 · Out of lives · 0 points
  • Level 2 · Out of lives · 3 points
  • Level 3 · Out of lives · 1 points

Watch the replay · Iceman Contributor, Foresight

Planning ahead: the two traps in Foresight

Watch on YouTube · Planning ahead: the two traps in Foresight

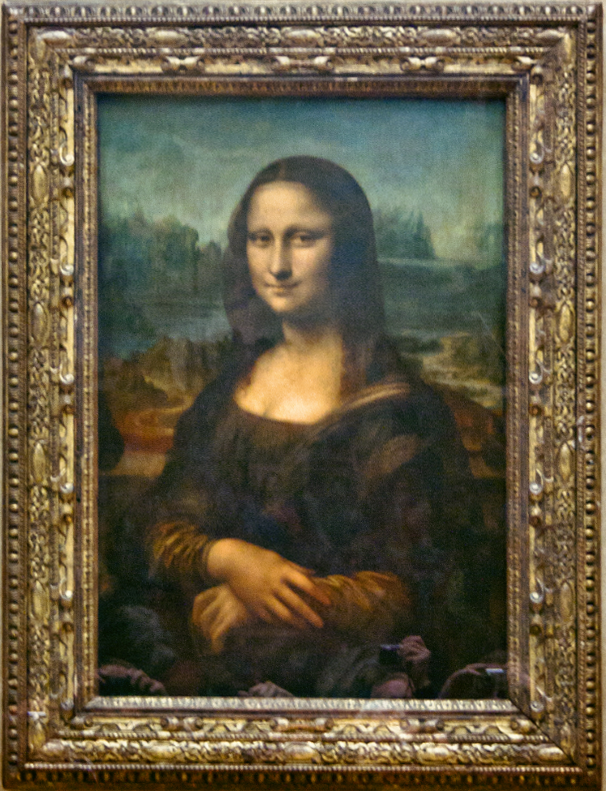
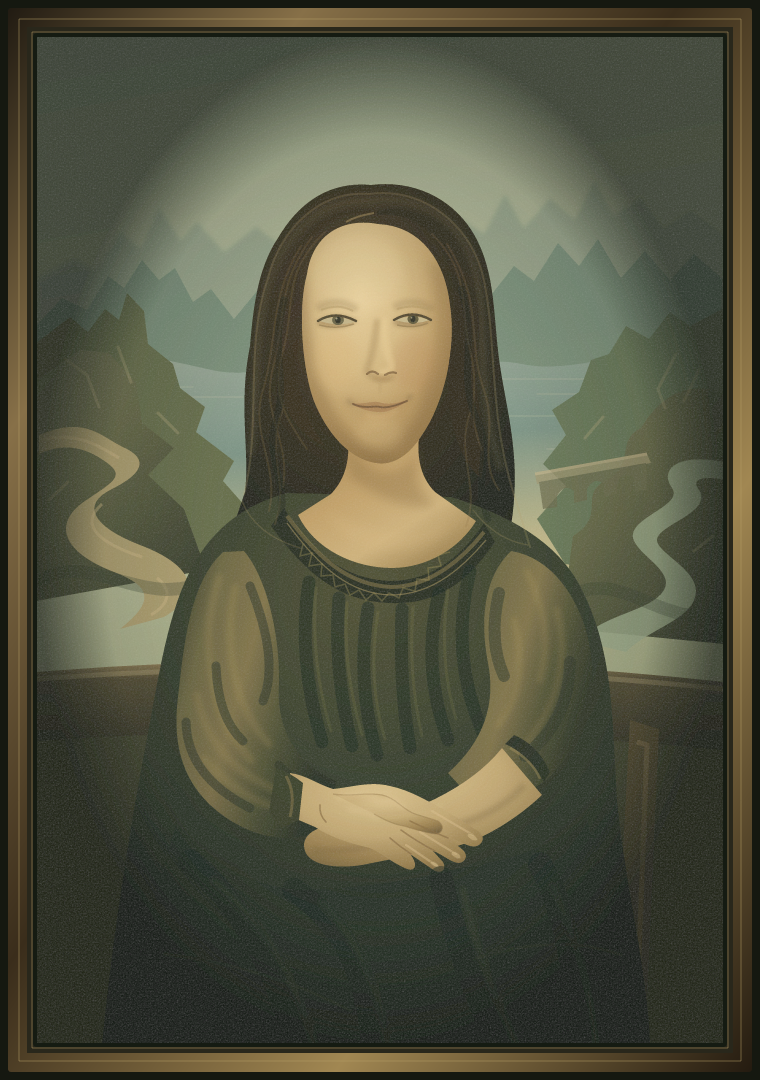
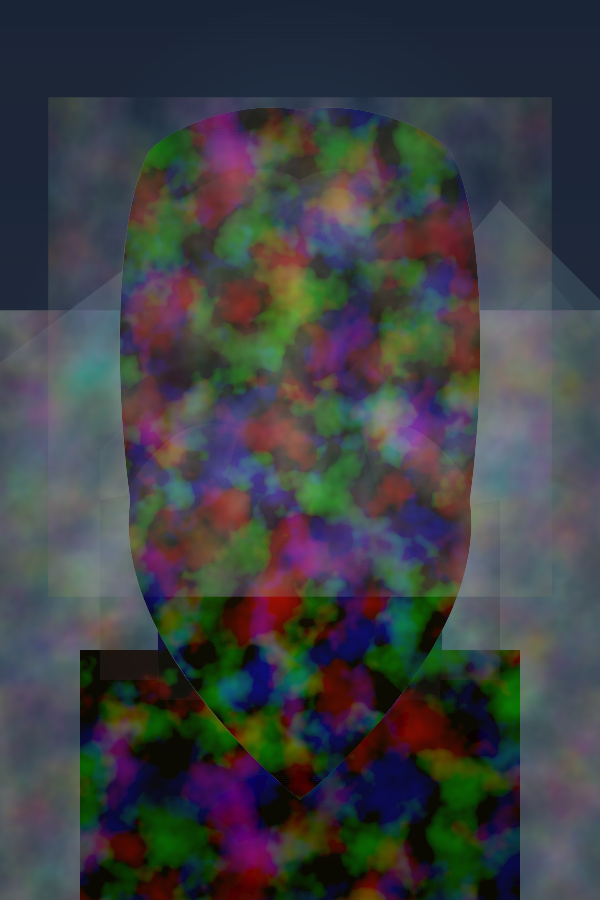
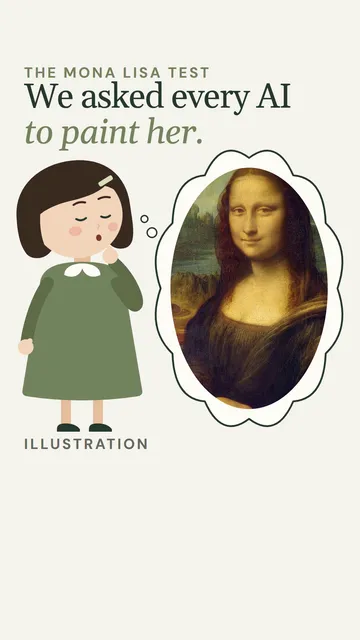
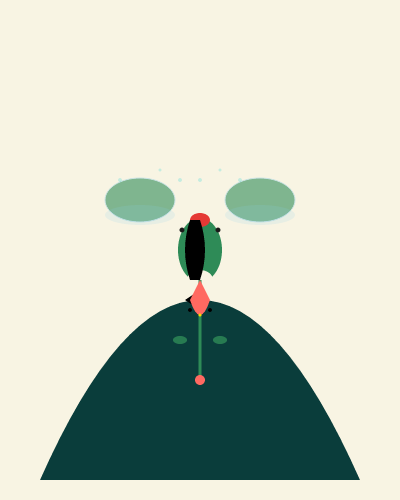
Mona Lisa: Can a model rebuild what it can describe perfectly?

A high score means the result preserves familiar proportions, expression, composition and light.

Reference
Reference for Mona Lisa

Highest score

GPT-6 Astra: Mona Lisa benchmark result

Benchmark score: 66.9 out of 100

Recorded 30 September 2026View result · GPT-6 Astra, Mona Lisa

Lowest score

Nemotron 3 Ultra: Mona Lisa benchmark result

Benchmark score: 0.5 out of 100

Recorded 4 October 2026View result · Nemotron 3 Ultra, Mona Lisa

Visual recall: the Mona Lisa from memory

Watch on YouTube · Visual recall: the Mona Lisa from memory

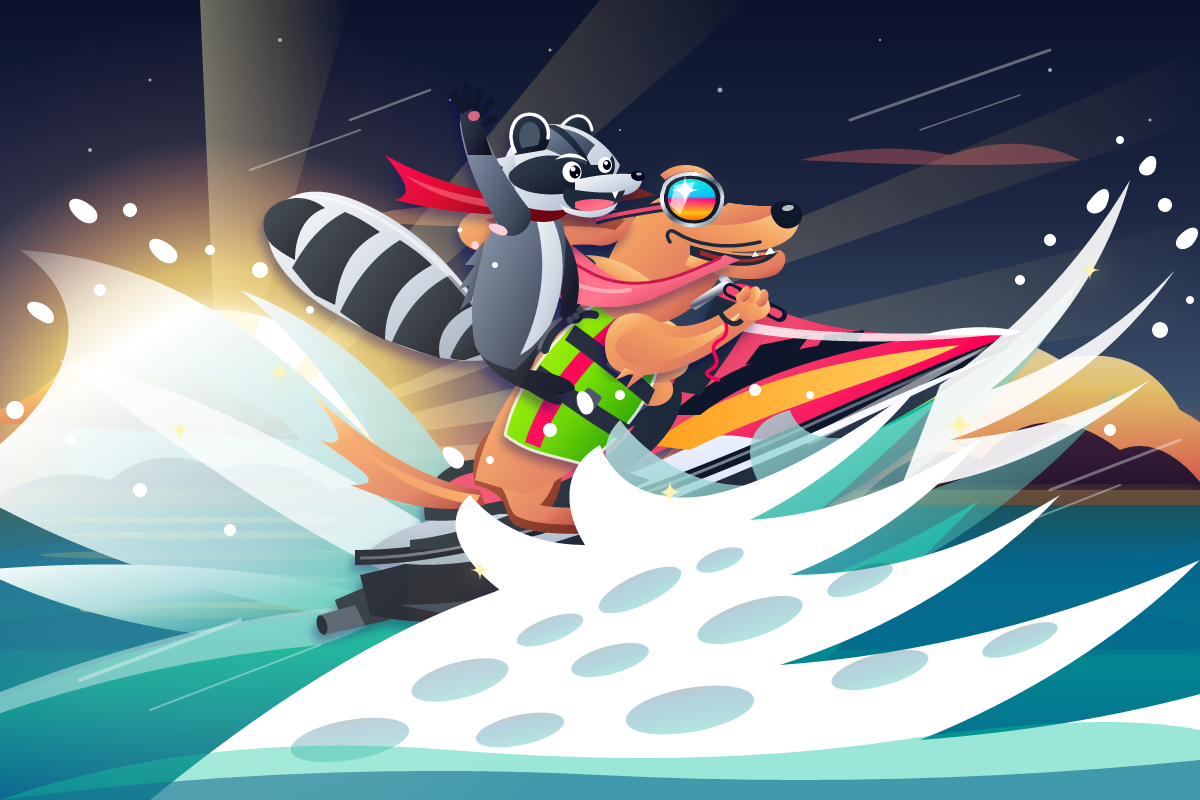
Raccoon: Can a model show characters actually doing something together?

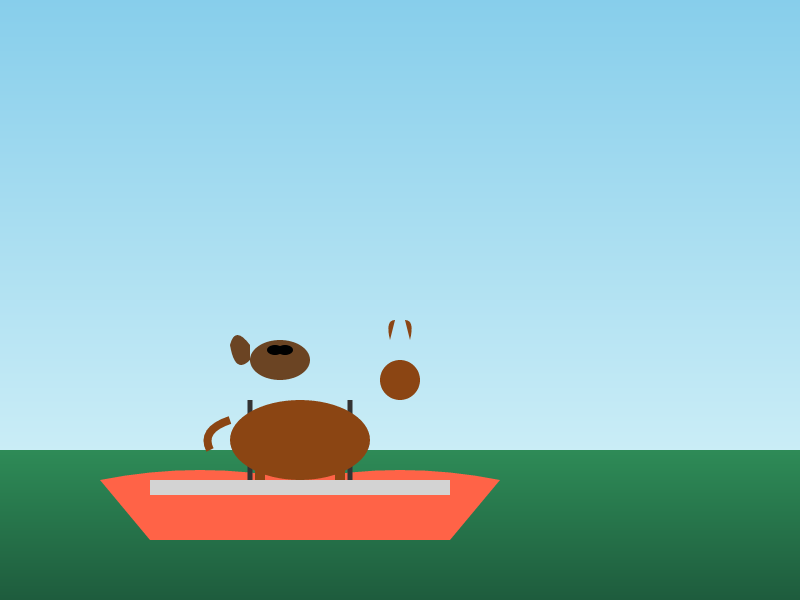
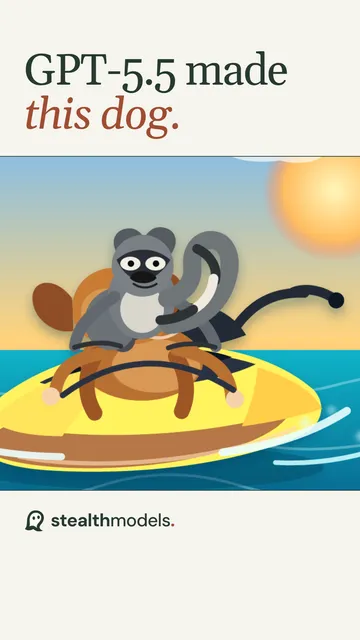
A high score means the dog, raccoon and jet ski connect through believable contact, perspective and motion.

Highest score

Gemini 4 Argon: Raccoon benchmark result

Benchmark score: 81.3 out of 100

Recorded 13 October 2026View result · Gemini 4 Argon, Raccoon

Lowest score

Kolibri-1: Raccoon benchmark result

Benchmark score: 10.0 out of 100

Recorded 5 October 2026View result · Kolibri-1, Raccoon

Play it yourself

The same levels and rules the models get. See where your score would place.

Foresight benchmark board

Foresight

Can you stay one step ahead of the ghosts?

Play Foresight
Latch benchmark board

Latch

Can you steer two robots without one careless push?

Play Latch